Categories
Every RL environment and AI benchmark carries one or more categories, so you can see where the field is crowded and where it is thin.
How categories are built
The sources tag their entries in their own vocabularies. Our synthesis step maps each raw tag to one canonical category, so “Code”, “coding” and “Software engineering” all become Coding. New tags are decided once by an AI agent from sample entries and cached in our repository. Until a decision exists, a simple rule title-cases the tag.
RL environments and AI benchmarks are different things: environments are where agents train, benchmarks are how they are measured. The homepage slide shows them as two separate views, each laid out from its own entries, so a category can be large in one and absent from the other.
An entry can carry several categories. On the slide, its first category is its home colony, and each of the others is a filament reaching out to that colony. A category whose entries all call another category home is a ghost colony: an outline with no cells of its own.
Categories come and go with the data. When a new one appears, it gets a page, an icon (or a neutral one until we draw it), a specimen plate for each kind of entry it holds and a draft definition on the next build.
All 22 categories
Snapshot 2026-10-10. Counts are entries tagged with the category, so an entry with three categories counts in each.
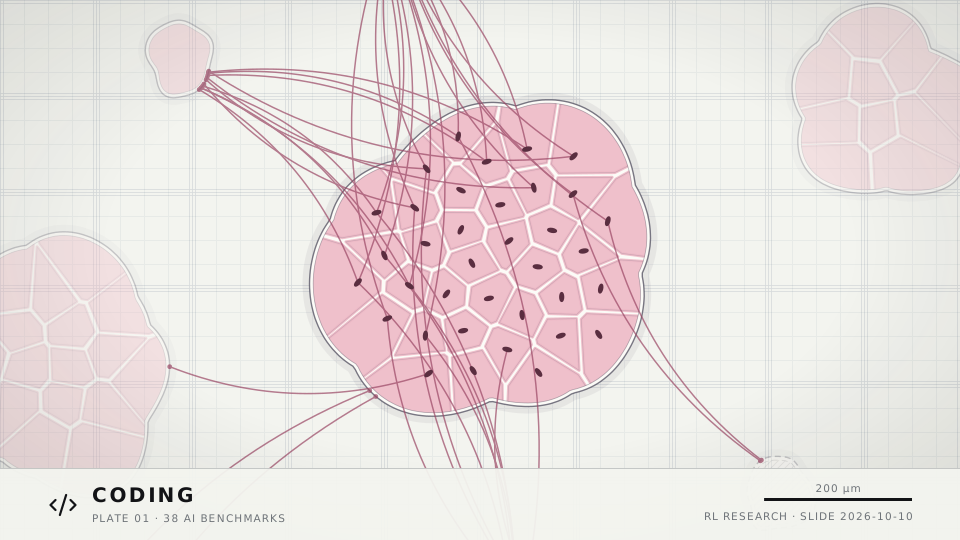 CodingSoftware engineering work: writing, fixing and reviewing code in real repositories and terminals. Entries usually grade a model by running the project's tests or checking the state of the repository afterward.
36 env · 38 bench
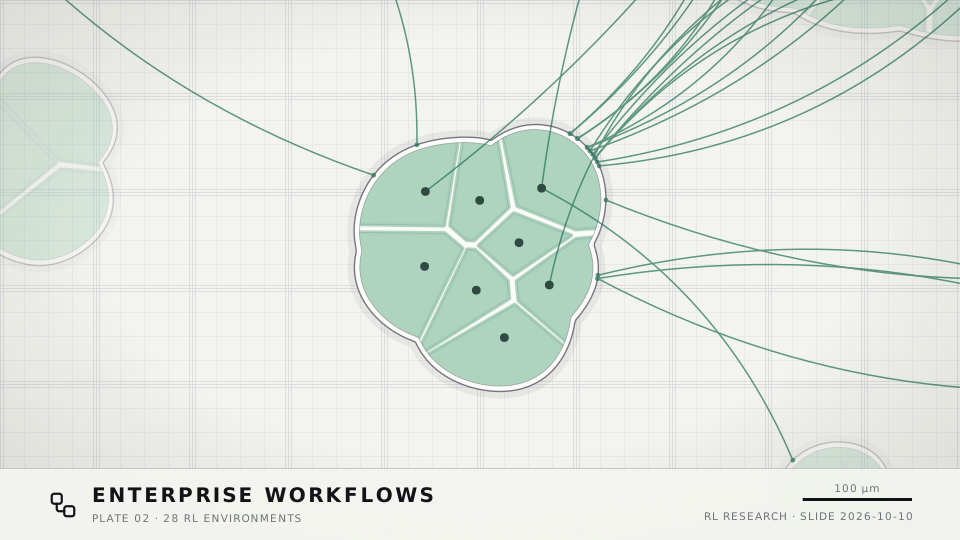 Enterprise WorkflowsMulti-step business tasks of the kind done inside companies: moving between documents, spreadsheets, internal tools and tickets to finish a job end to end.
28 env · 17 bench
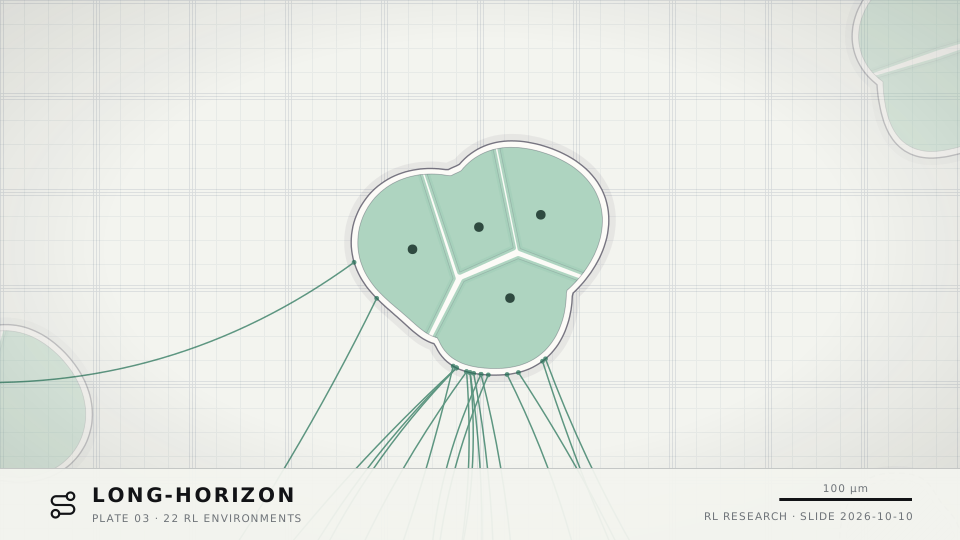 Long-HorizonTasks that take many steps or a long session to finish, where a model has to plan, keep track of state and recover from its own mistakes before the work is done.
22 env · 12 bench
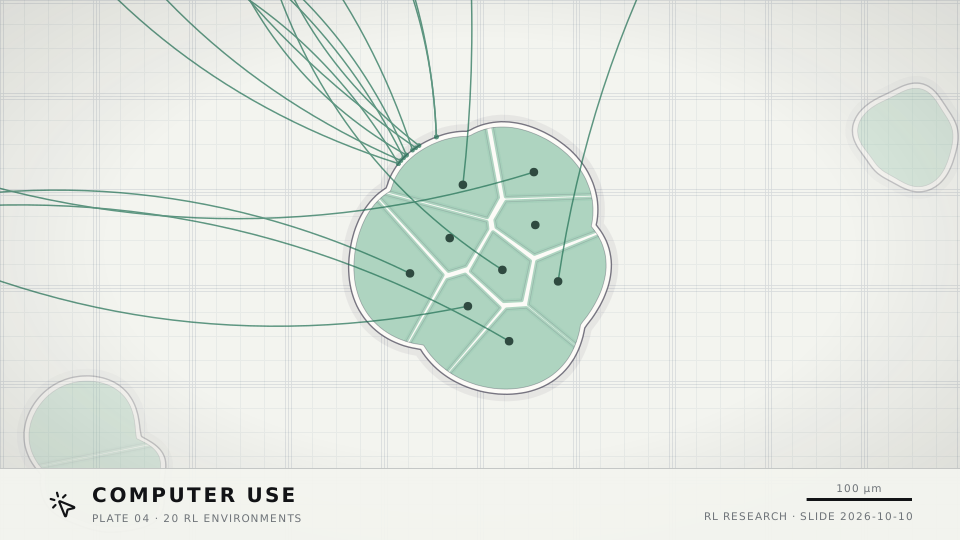 Computer UseOperating real software through its interface: clicking, typing and navigating desktops, browsers and apps the way a person at a keyboard would.
20 env · 12 bench
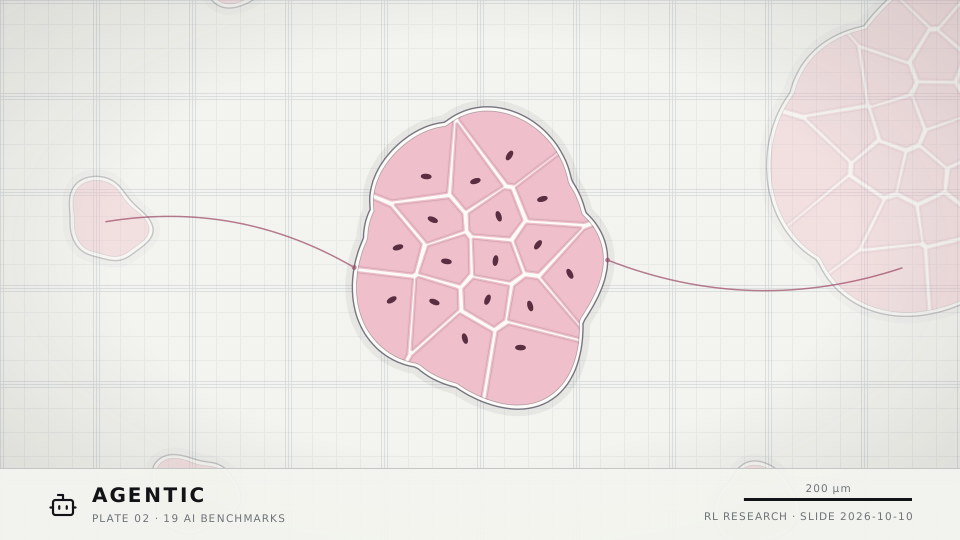 AgenticModels acting as agents: taking actions in a terminal, browser or tool environment over several turns to reach a goal, rather than answering a single prompt.
0 env · 19 bench
 MathMathematical problem solving, from grade-school word problems to competition and research-level questions, usually graded against an exact final answer.
4 env · 10 bench
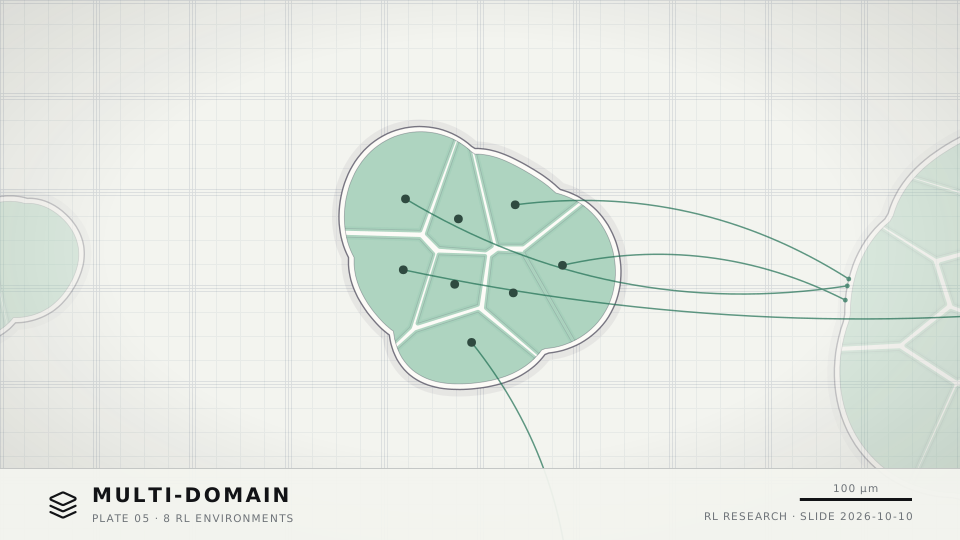 Multi-DomainBuilders and suites that span many subject areas at once, such as expert networks covering several professions and benchmarks that mix coding, finance and other professional work.
8 env · 4 bench
 Private CodebasesCoding work inside proprietary repositories rather than public open-source projects, to test how models handle unfamiliar company code they have never seen.
7 env · 2 bench
 MLMachine learning engineering itself: training and evaluating models, building data pipelines, tuning experiments and debugging the results.
4 env · 1 bench
 ScienceScientific research work, such as handling lab and biological data, reading the literature and reasoning about experiments.
3 env · 2 bench
 KnowledgeFactual and expert knowledge across many subjects, tested with closed-book questions that each have one verifiable answer.
0 env · 3 bench
 SecurityOffensive and defensive security work: finding and exploiting vulnerabilities, hardening systems and running penetration tests against sandboxed targets.
3 env · 0 bench
 Chip DesignHardware engineering for semiconductors: writing and verifying hardware description code and working through the stages of the chip design flow.
2 env · 0 bench
 CreativeCreative and aesthetic work, such as images, style and taste, where output is judged by people rather than by an automatic check.
2 env · 0 bench
 FinanceFinancial analysis and operations, such as building models, reading filings and working with market and accounting data.
2 env · 0 bench
 HealthcareClinical and health-data tasks, such as working with patient records in standard formats and answering medical questions.
1 env · 1 bench
 Tool UseCalling external tools and APIs correctly: choosing the right function, passing valid arguments and using the results to finish a task.
2 env · 0 bench
 AlignmentSteering model behavior toward human intent and preferences, through preference data, reward models and evaluations of safe, helpful responses.
1 env · 0 bench
 AudioSpeech and sound: transcribing, understanding and generating audio.
1 env · 0 bench
 MultilingualWork in languages other than English, measuring whether a model's knowledge and skills carry across languages.
0 env · 1 bench
 ReasoningHard reasoning problems built to resist memorization, such as graduate-level science questions and abstract visual puzzles.
0 env · 1 bench
 SearchFinding information on the open web: browsing, following links and combining scattered facts into one answer.
0 env · 1 bench