

Bridging VideoQA and Video-Guided Agentic Tasks via Generalized Keyframe Extraction D
AI benchmark · Gui
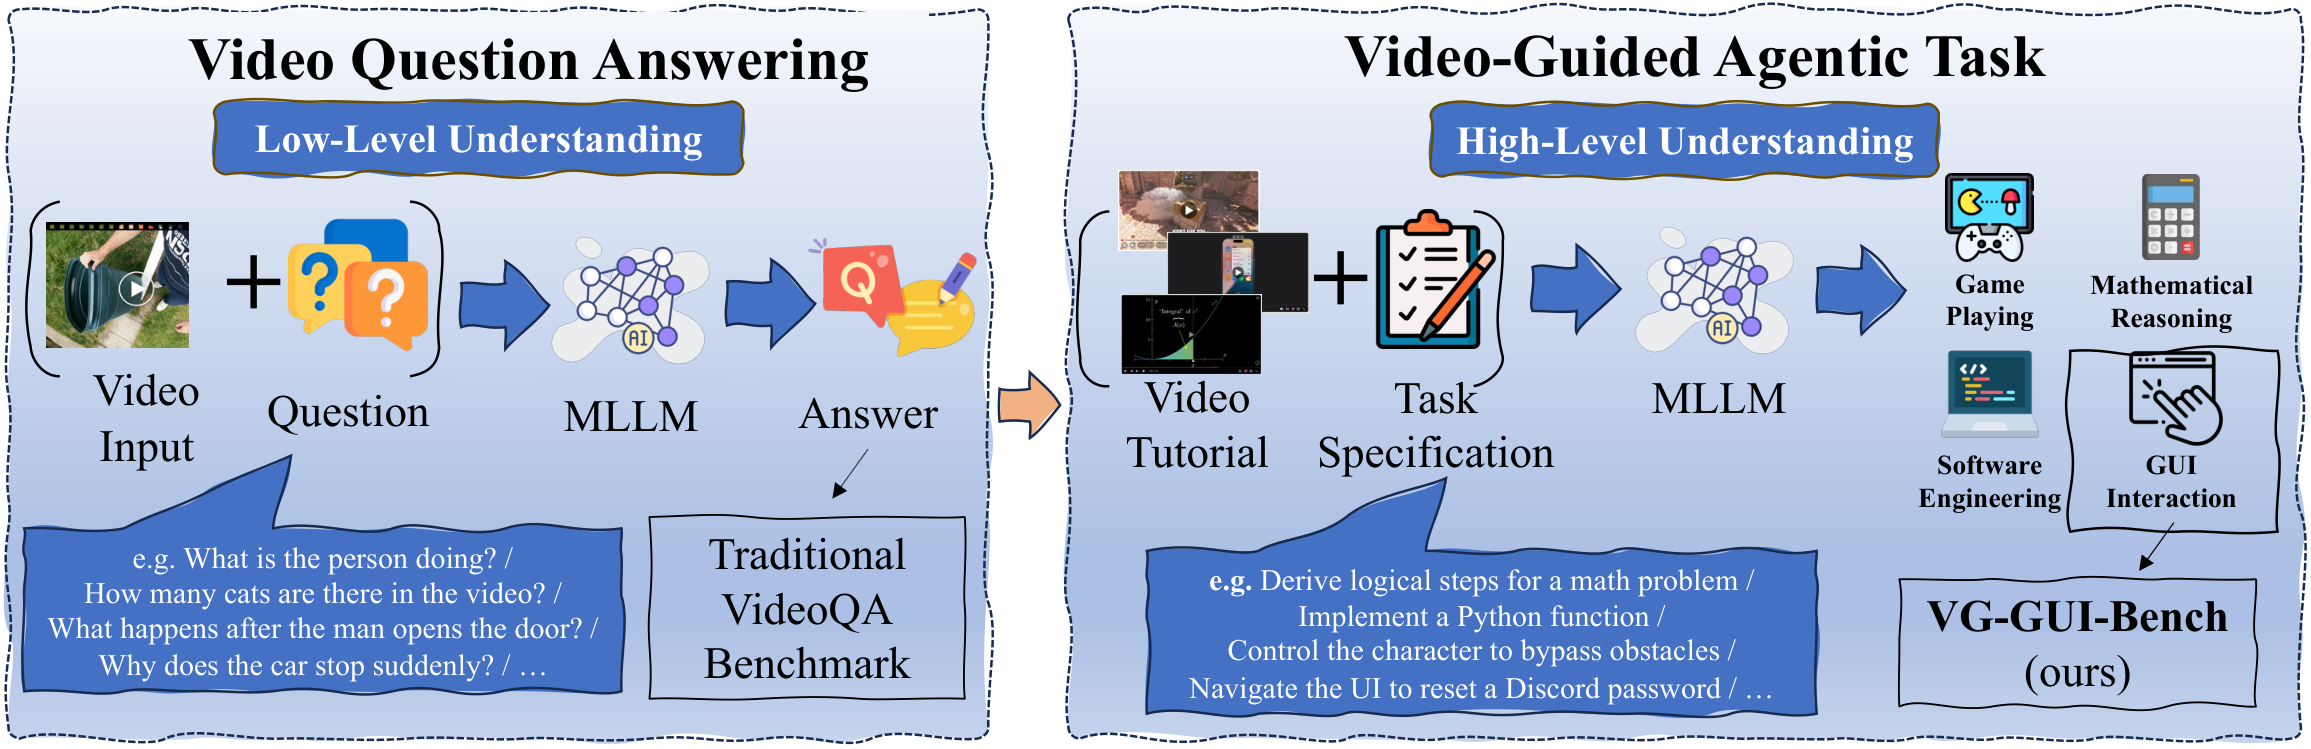
What is Bridging VideoQA and Video-Guided Agentic Tasks via Generalized Keyframe Extraction?
Video understanding is a fundamental capability for multimodal intelligence, and recent Multimodal Large Language Models (MLLMs) have achieved remarkable performance on Video Question Answering (VideoQA) benchmarks. However, existing benchmarks primarily evaluate whether models can perceive shallow visual cues, while rarely examining whether MLLMs can learn deeper knowledge or procedural skills from video tutorials and generalize them to downstream long-horizon agentic tasks. To address this gap, we introduce VG-GUIBench (Video-Guided GUI Benchmark), a new benchmark designed to evaluate whether MLLM-based GUI agents can follow video tutorials to complete corresponding GUI interactive tasks. Furthermore, we observe that the performance of models on both VideoQA and video-guided agentic tasks critically depends on effective keyframe extraction. Based on this observation, we propose TASKER (Task-driven And Scene-aware Keyframe searchER), a keyframe extraction algorithm that jointly considers task relevance and scene dynamics to identify informative frames. Experimental results demonstrate that TASKER achieves significant performance improvements on both VideoQA and video-guided agentic task benchmarks, outperforming the best baseline by 2.0% on the EgoSchema fullset and 1.8% on the NExT-QA dataset, respectively. These results further highlight the potential of generalized keyframe extraction methods for video understanding tasks. Our code and data are available at https://github.com/VG-GUI-TASKER/VG-GUI-TASKER.
Tier D
Long tail: little or no usage data yet.
How much stands behind a tier: usage, who backs it, a confirmed line from its own site or paper, and a clear read on X. High with three of the four, medium with two, low otherwise.
- 11 models scored
- no proper name (a paper title or description)
- in curated RL directories (1 pt)
How we got to tier D
- Adoption: 11 models scored; no proper name (a paper title or description). Tier D.
- Not yet read on X.
- In curated RL directories: 1 point, a floor of none.
- Not yet confirmed by a line from its own site or paper.
A clear view on X moves a tier one step up or down; most entries don't move. How tiers work.
Not on the map yet: no line from its own site or paper places it in a domain.
Next: browse all benchmarks. Entry from the RL Research daily scrape of public sources, 2026-10-11 snapshot.