


ClawBench B
AI benchmark · Agentic
What is ClawBench?
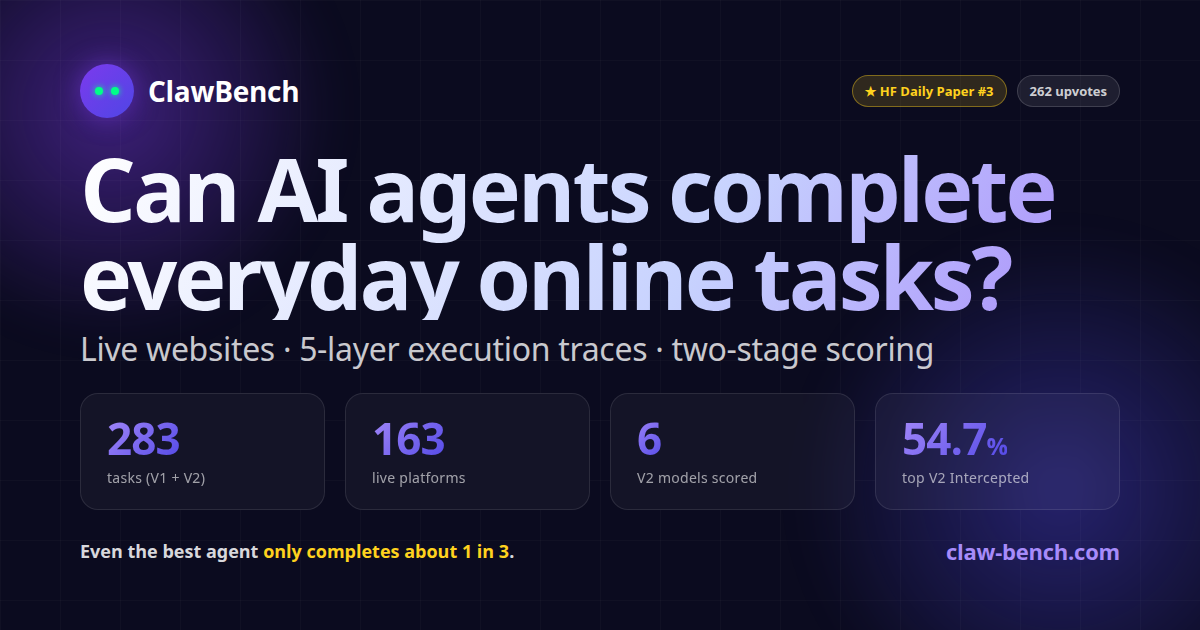
Open benchmark for evaluating AI browser agents on realistic everyday tasks across live websites, including travel booking, food ordering, job applications, email, shopping, and other multi-step online workflows. Runs are graded first by whether the final HTTP request matched the task schema and then by whether an LLM judge found that payload fulfilled the instruction.
Tier B
Established: 15 or more models scored, or curated RL directories rate it.
How much stands behind a tier: usage, who backs it, a confirmed line from its own site or paper, and a clear read on X. High with three of the four, medium with two, low otherwise.
- 37 models scored
- in curated RL directories (1 pt)
How we got to tier B
- Adoption: 37 models scored. Tier B.
- On X: unclear, none buzz No move.
- In curated RL directories: 1 point, a floor of none.
- Not yet confirmed by a line from its own site or paper.
A clear view on X moves a tier one step up or down; most entries don't move. How tiers work.
Not on the map yet: no line from its own site or paper places it in a domain.
Next: browse all benchmarks. Entry from the RL Research daily scrape of public sources, 2026-10-11 snapshot.