


MAS-PromptBench C
AI benchmark · Uncategorized
- Domains
- Uncategorized
- Tier
- C why
- Snapshot
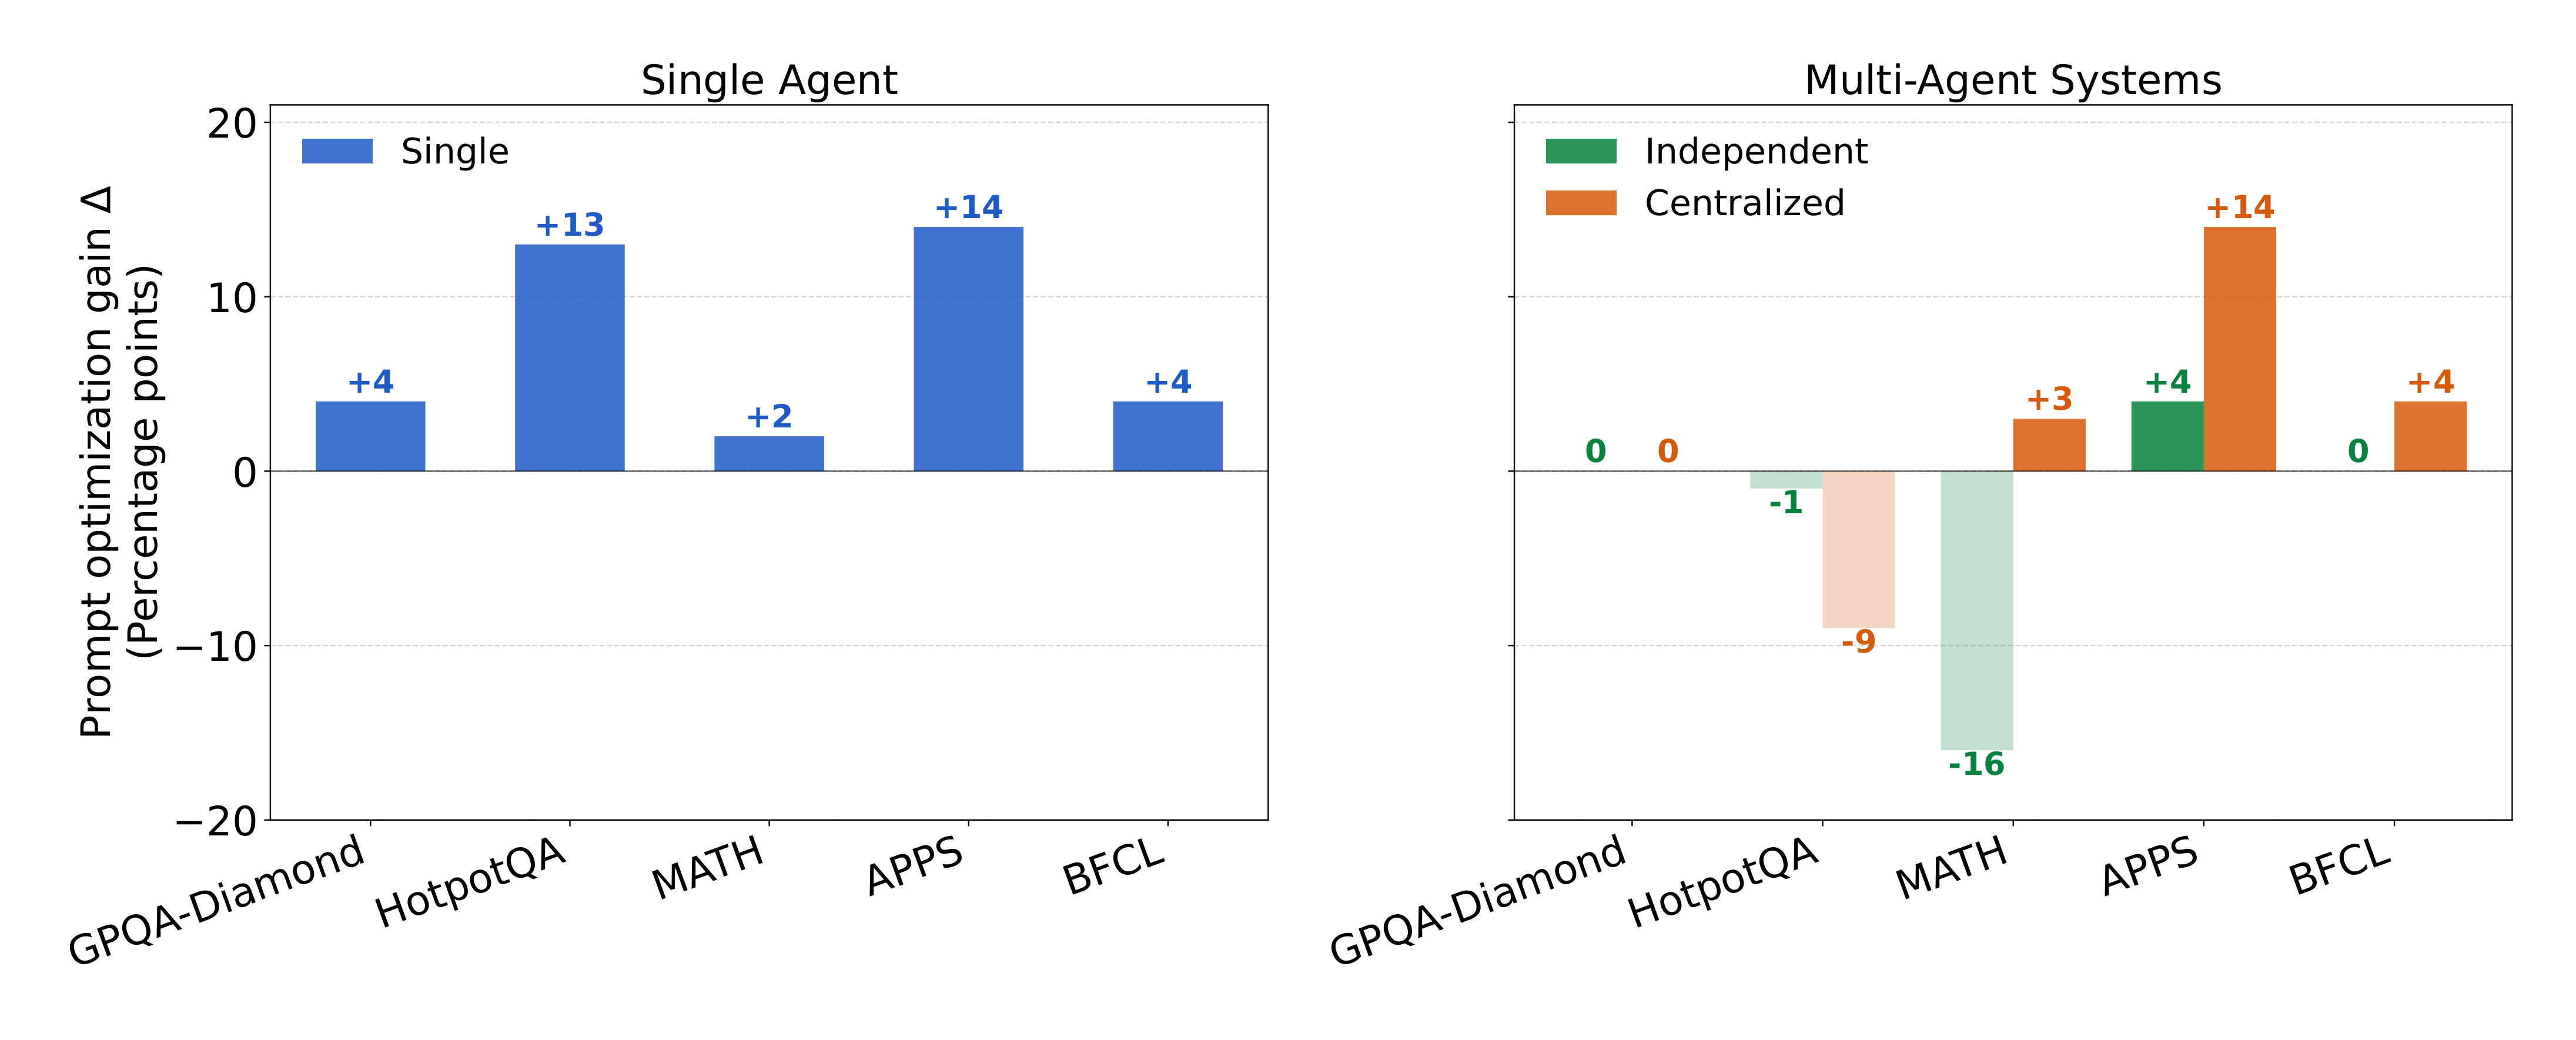
Full listing name: MAS-PromptBench: When Does Prompt Optimization Improve Multi-Agent LLM Systems?
What is MAS-PromptBench?
Multi-agent systems (MAS) offer a scalable path forward for agentic AI, comprising multiple LLM-based agents, each assigned a system prompt and a position within a workflow that governs inter-agent coordination and output aggregation. System prompts thus form a critical and accessible optimization surface: they specify agents' roles and behaviors, enabling system-level improvements without model finetuning. Although prompt optimization has shown substantial potential for single LLMs, extending it to MAS poses distinct challenges, notably an exponentially growing search space. It remains unclear whether, when, and by how much prompt optimization improves MAS performance, and how sensitive such gains are to system configuration. In this work, we systematically study system-prompt optimization across a broad range of MAS setups varying in task, workflow, communication protocol, and team size, benchmarking two prompt optimizers that naturally extend state-of-the-art single-agent methods. The results reveal its potential to unlock significant gains while exposing open challenges, characterizing when and how much prompt optimization helps across diverse MAS settings.
Tier C
Niche: a handful of models scored, or built by an RL vendor.
How much stands behind a tier: usage, who backs it, a confirmed line from its own site or paper, and a clear read on X. High with three of the four, medium with two, low otherwise.
- 9 models scored
- in curated RL directories (1 pt)
How we got to tier C
- Adoption: 9 models scored. Tier C.
- Not yet read on X.
- In curated RL directories: 1 point, a floor of none.
- Not yet confirmed by a line from its own site or paper.
A clear view on X moves a tier one step up or down; most entries don't move. How tiers work.
Not on the map yet: no line from its own site or paper places it in a domain.
Next: browse all benchmarks. Entry from the RL Research daily scrape of public sources, 2026-10-11 snapshot.