

MUSE B
AI benchmark · Software Engineering
- Publisher
- Paper Arxiv
- Domains
- Software Engineering
- Tier
- B why
- Snapshot
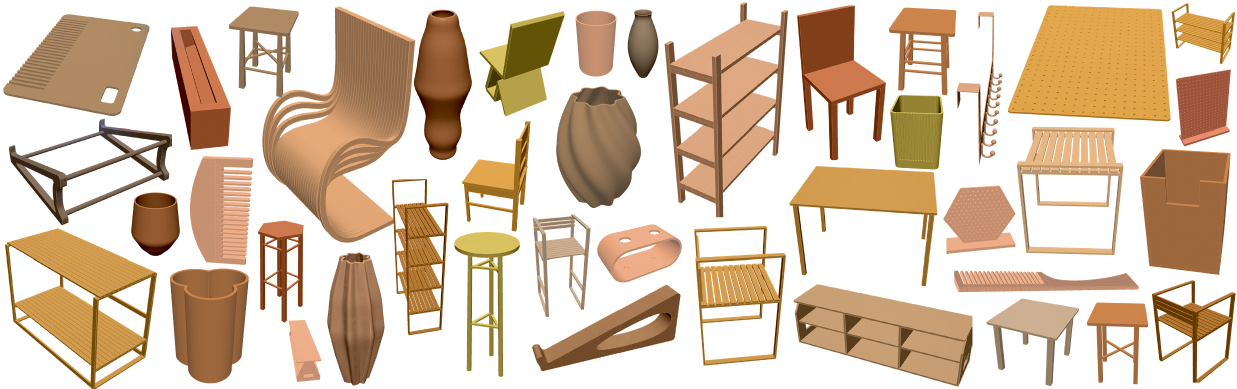
Full listing name: MUSE: Benchmarking Manufacturable, Functional, and Assemblable Text-to-CAD Generation
What is MUSE?
Large language models (LLMs) have recently advanced text-driven 3D generation, yet Text-to-CAD remains far from supporting industrial product design. Existing benchmarks focus primarily on generating single-part CAD models and evaluate them using geometric similarity metrics that fail to capture functionality, manufacturability, and assemblability. To address this gap, we introduce MUSE, a Text-to-CAD benchmark focused on complex, editable boundary representation (B-Rep) assemblies. MUSE pairs practical design instances with structured Design Specifications and evaluates generated models through a three-stage protocol: code check, geometric check, and design-intent alignment. The final stage uses design-specific rubrics to assess functionality, manufacturability, and assemblability, moving beyond shape matching toward practical design quality. To enable scalable evaluation, we use a rubric-based visual language model (VLM) judge and validate its reliability through human annotation. Experiments on closed-source and open-source LLMs reveal a clear failure cascade from executable code to valid geometry and finally to engineering-ready design, with even the strongest models achieving limited success on fine-grained engineering criteria. Together, MUSE provides a realistic benchmark and evaluation framework for advancing Text-to-CAD from geometric generation toward true engineering design. Our project website, including the leaderboard, dataset, and code, is available at https://dong7313.github.io/muse-benchmark/.
Tier B · a leaderboard, listed apart
Established: 15 or more models scored, or curated RL directories rate it.
How much stands behind a tier: usage, who backs it, a confirmed line from its own site or paper, and a clear read on X. High with three of the four, medium with two, low otherwise.
- 15 models scored
- in curated RL directories (1 pt)
How we got to tier B
- Adoption: 15 models scored. Tier B.
- Not yet read on X.
- In curated RL directories: 1 point, a floor of none.
- Not yet confirmed by a line from its own site or paper.
- Judged a leaderboard, arena or index rather than one benchmark (or not a benchmark at all): listed apart.
A clear view on X moves a tier one step up or down; most entries don't move. How tiers work.
Not on the map yet: no line from its own site or paper places it in a domain.
Next: browse all benchmarks. Entry from the RL Research daily scrape of public sources, 2026-10-11 snapshot.