


PhyGround C
AI benchmark · Video
What is PhyGround?
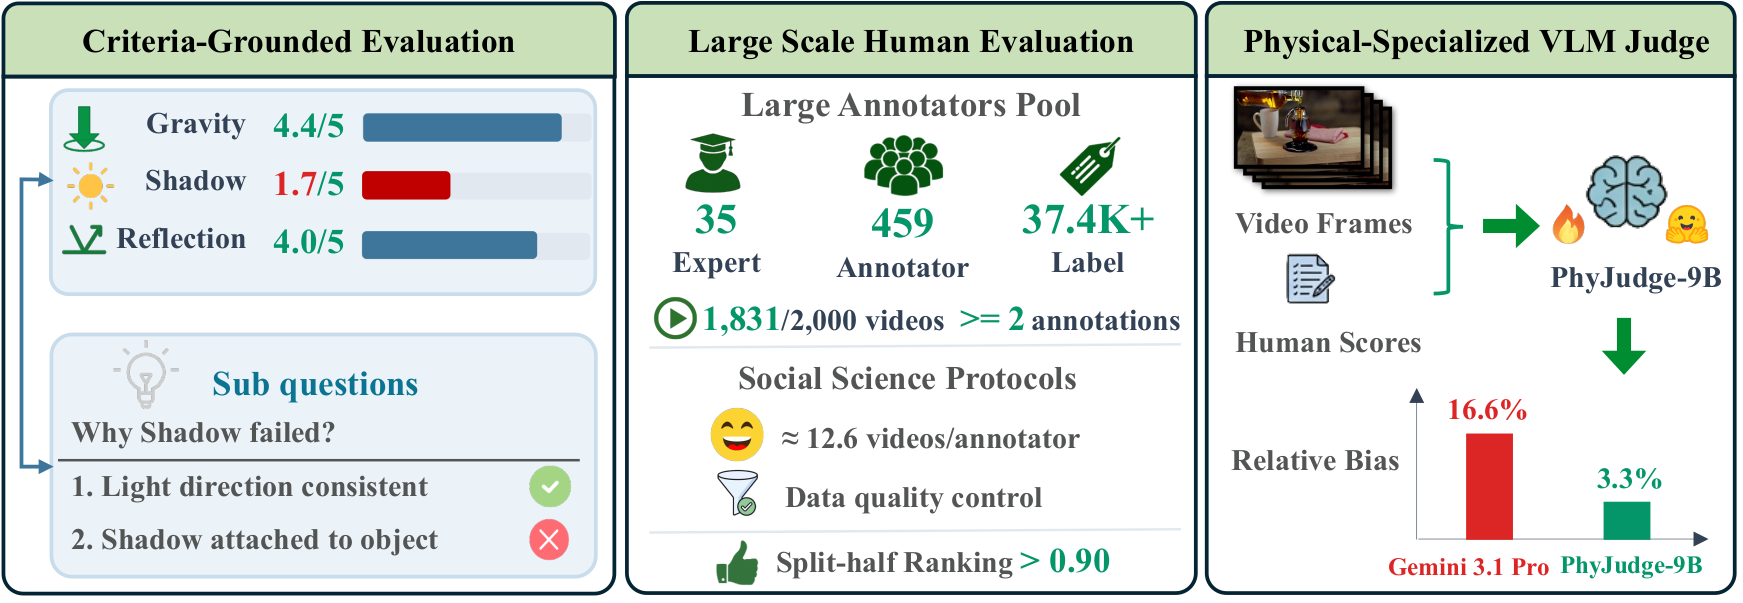
Generative world models are increasingly used for video generation, where learned simulators are expected to capture the physical rules that govern real-world dynamics. However, evaluating whether generated videos actually follow these rules remains challenging. Existing physics-focused video benchmarks have made important progress, but they still face three key challenges, including the coarse evaluation frameworks that hide law-specific failures, response biases and fatigue that undermine the validity of annotation judgments, and automated evaluators that are insufficiently physics-aware or difficult to audit. To address those challenges, we introduce PhyGround, a criteria-grounded benchmark for evaluating physical reasoning in video generation. The benchmark contains 250 curated prompts, each augmented with an expected physical outcome, and a taxonomy of 13 physical laws across solid-body mechanics, fluid dynamics, and optics. Each law is operationalized through observable sub-questions to enable per-law diagnostics. We evaluate eight modern video generation models through a large-scale, quality-controlled human study, grounded on social science lab experiment design. A total of 459 annotators provided 5,796 complete annotations and over 37.4K fine-grained labels; after quality control, the retained annotations exhibited high split-half model-ranking correlations (Spearman's rho > 0.90). To support reproducible automated evaluation, we release PhyJudge-9B, an open physics-specialized VLM judge. PhyJudge-9B achieves substantially lower aggregate relative bias than Gemini-3.1-Pro (3.3% vs. 16.6%). We release prompts, human annotations, model checkpoints, and evaluation code on the project page https://phyground.github.io/.
Tier C
Niche: a handful of models scored, or built by an RL vendor.
How much stands behind a tier: usage, who backs it, a confirmed line from its own site or paper, and a clear read on X. High with three of the four, medium with two, low otherwise.
- 8 models scored
- in curated RL directories (1 pt)
How we got to tier C
- Adoption: 8 models scored. Tier C.
- Not yet read on X.
- In curated RL directories: 1 point, a floor of none.
- Not yet confirmed by a line from its own site or paper.
A clear view on X moves a tier one step up or down; most entries don't move. How tiers work.
Not on the map yet: no line from its own site or paper places it in a domain.
Next: browse all benchmarks. Entry from the RL Research daily scrape of public sources, 2026-10-11 snapshot.