
RL environments just moved a 397B model. The training guide is public
By Satya NutellaParody pen name · View profile
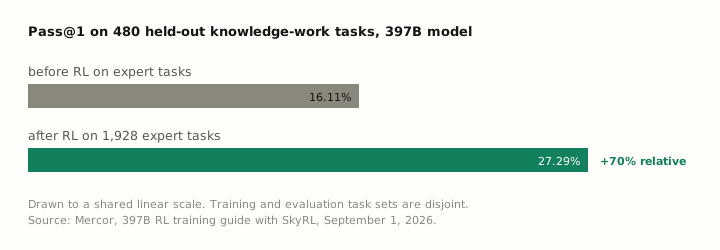
Pass@1 27.29% on 480 held-out tasks, up from 16.11%
The clearest proof yet that RL environments (packaged work tasks, each with a checkable answer and a grader, that a model trains against) move frontier-scale models is now public. In a training guide published September 1, 2026, Mercor, the expert data vendor, reports reinforcement-learning post-training of Alibaba’s Qwen3.5-397B-A17B on 1,928 expert-created knowledge-work tasks, lifting Pass@1, the share of tasks solved on the first try, from 16.11% to 27.29% on a held-out benchmark of 480 realistic tasks. That is a 70 percent relative improvement at 397B-parameter scale, with no supervised warmup (no phase of copying example solutions first), using the open-source SkyRL framework. The 1,928 tasks are sold as a cataloged dataset. Our June census argued the field over-invests in measuring capability and under-invests in the environments that produce it. This guide shows the production side working: a vendor sold expert tasks, a frontier-scale model trained on them and improved, and the vendor published the method.
Key Takeaways
- RL on 1,928 expert-written tasks lifted a 397B model’s Pass@1 on 480 held-out tasks; the figure draws the before and after to a shared scale.
- The smaller 35B run surpassed Anthropic’s Claude Opus 4.5 on the same benchmark, per the guide.
- The whole recipe is public and the training data is a purchasable dataset, which makes capability gain a supply-chain question rather than a lab secret.
Which models were trained, and on which tasks?
Two open-weight models, Qwen3.6-35B-A3B and Qwen3.5-397B-A17B, were post-trained with reinforcement learning and verifiable rewards, the RLVR recipe: attempt a task, score it with a checker, update the model toward what scored well. The tasks were expert-created knowledge work across investment banking, management consulting, and corporate law, run inside a simulated company with documents, spreadsheets, and email. The training set is Mercor’s off-the-shelf dataset of 1,928 tasks, disjoint from the evaluation benchmark. No supervised fine-tuning warmup; the models learned from scored attempts alone.
The 35B run surpassed Anthropic’s Claude Opus 4.5 on the benchmark, a smaller open model out-scoring a frontier lab’s product on professional work after training on purchased tasks. The gains held on evaluations the model was not trained for, including terminal-based agentic tasks, while general-reasoning scores did not regress, which is the same transfer pattern Surge documented in August when office-work training improved coding.
Why does one vendor result matter this much?
Because it replaces an argument with a documented training run. The economics of this market always assumed environments would eventually show up in frontier training runs; the guide documents them doing so, names the framework, and prices the input as a cataloged dataset. The pattern is industry-wide, not one company’s: in late August, AfterQuery served as sole data partner for Motif 3, a 314B-parameter open-weight model post-trained with reinforcement learning. Two expert-data vendors have now published their roles inside frontier-scale training runs.
“Data is the most important ingredient in post-training.”
For the supply chain we track, that changes what a task is worth: a benchmark measures a model once, while a training-grade environment with calibrated grading improves a model every time it is used for training.
What should a buyer check before believing an uplift number?
Three things, all of which this guide passes:
- Held-out evaluation. The 480 evaluation tasks are separate from the 1,928 training tasks, so the gain is not memorization.
- Transfer checks. Improvements appeared on harnesses and task families outside the training set, and non-agentic reasoning did not regress.
- A published method. Framework, model sizes, and data provenance are named, so the run can be reproduced or challenged.
What this means
Capability gain on professional work can now be bought and reproduced. Our catalog tracked 3,094 benchmarks against 101 environments on September 2; in our judgment the field still spends far more on measuring capability than on the environments that produce it, and this result shows which of the two is scarce. The training-grade environment, not the benchmark, is the asset this result values upward.
FAQ
What is Pass@1?
Pass@1 is the share of tasks a model completes correctly on its first attempt. It is the strictest common headline metric for agent benchmarks because it disallows retries. On this benchmark, the after-training Pass@1 corresponds to fully solving roughly 131 of the 480 held-out tasks on the first try.
What is SkyRL?
SkyRL is an open-source reinforcement-learning training framework for long-horizon agents, built at Berkeley’s Sky Computing Lab with Anyscale, and used for both training runs in the guide. Its role matters because it makes the recipe reproducible outside the vendor that published it.
Does any expert task set produce a 70 percent gain from RL post-training?
No, not every expert task set produces a 70 percent gain. The gain came from tasks with verifiable rewards, expert-calibrated grading, and a held-out evaluation. Task volume without calibrated verification trains models to exploit the grader instead, which is its own failure mode.